Topics
Menu
About
Advertise
Contact
All
AI Mode
News / Articles
Web
Shopping
Websites
Images
Videos
Privacy Policy
Your Privacy Choices
Terms of Use
Data Licensing
Accessibility
Install app (Android)
Add to Home Screen (iPhone)
Install
Close
Searching:
/software-development/ai-ml-engineering-and-llmops/frameworks-and-training/
1 hour
4 hours
8 hours
12 hours
24 hours
3 days
7 days
14 days
30 days
90 days
180 days
365 days
2 years
All
Published
Discovered
Title & Body (Meaning)
Title & Desc. (Meaning)
Title (Meaning)
Meta Tags (Meaning)
Title/Body (Text & Meaning)
Title/Desc. (Text & Meaning)
Title (Text & Meaning)
Meta_Information (Text & Meaning)
Title/Body (Text)
Title/Desc. (Text)
Title (Text)
Description (Text)
Meta (Text)
Meta Related (Text)
People (Text)
People Related (Text)
Organizations (Text)
Organizations Related (Text)
People/Organizations (Text)
People/Organizations Related (Text)
Places (Text)
Stock Symbols (Text)
Criminal Charges (Text)
AI Mode
All
Web
News
Shopping
Websites
Images
Videos
Topics
Topics
Sort
Default
A–Z
Coverage
Size
All
News (General)
People and Society
Politics
Law & Government
Conflict, War & Peace
Crime & Law
Business & Finance
Industrial
Real Estate
Science & Technology
Internet & Telecom
Computers & Electronics
Computer Hardware
Consumer Electronics
Software
Health
Education & Jobs
Religion
History
Human Interest
Social Life
Online Communities
Entertainment
Games
Books & Literature
Art & Design
Sports
Autos & Vehicles
Transportation
Travel & Tourism
Food & Dining
Fashion & Beauty
Home and Garden
Home & Hobbies
Lifestyle & Leisure
Shopping
Pets and Animals
Accidents & Emergencies
Weather
Images
79 images
Featured images from indexed articles. Click a picture for the article.
Gradient Descent: A Beginner’s Complete Guide to How Machines Learn
Gradient Descent: A Beginner’s Complete Guide to How Machines Learn
Medium
16+ hour ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Implementation of Machine Learning Workflows with NVIDIA cuML, RAPIDS, GPU Benchmarking, E
Implementation of Machine Learning Workflows with NVIDIA cuML, RAPIDS, GPU Benchmarking, Explainability, Clustering, and Model Inference
MarkTechPost
1+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Rendering live broadcast graphics without a GPU, and what four hours actually cost
Rendering live broadcast graphics without a GPU, and what four hours actually cost
DEV Community
2+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
ROCm vs Vulkan for AMD Local LLM Hosting: 2026 Guide
ROCm vs Vulkan for AMD Local LLM Hosting: 2026 Guide
DEV Community
2+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
CIQ Moves RLC Pro AI to Linux 6.18 to Improve AI Infrastructure Performance
CIQ Moves RLC Pro AI to Linux 6.18 to Improve AI Infrastructure Performance
HPCwire
3+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
AI Fixes Linux Bottlenecks Using “Hideous” Code » Linux Magazine
AI Fixes Linux Bottlenecks Using “Hideous” Code » Linux Magazine
Linux Magazine
3+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Gemma 4 on an Old 4 GB Laptop GPU: QAT Takes It From 9.5 GiB to 1.6
Gemma 4 on an Old 4 GB Laptop GPU: QAT Takes It From 9.5 GiB to 1.6
DEV Community
3+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
2B Gemma 4 Deployment with Cloud Run, NVIDIA L4, MCP SDK 2.x, and Claude Code
2B Gemma 4 Deployment with Cloud Run, NVIDIA L4, MCP SDK 2.x, and Claude Code
DEV Community
3+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM
Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM
n1n.ai
4+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
How I Built a C++20 Quantum Simulation Platform with 3D Bloch WebGL Telemetry
How I Built a C++20 Quantum Simulation Platform with 3D Bloch WebGL Telemetry
DEV Community
6+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
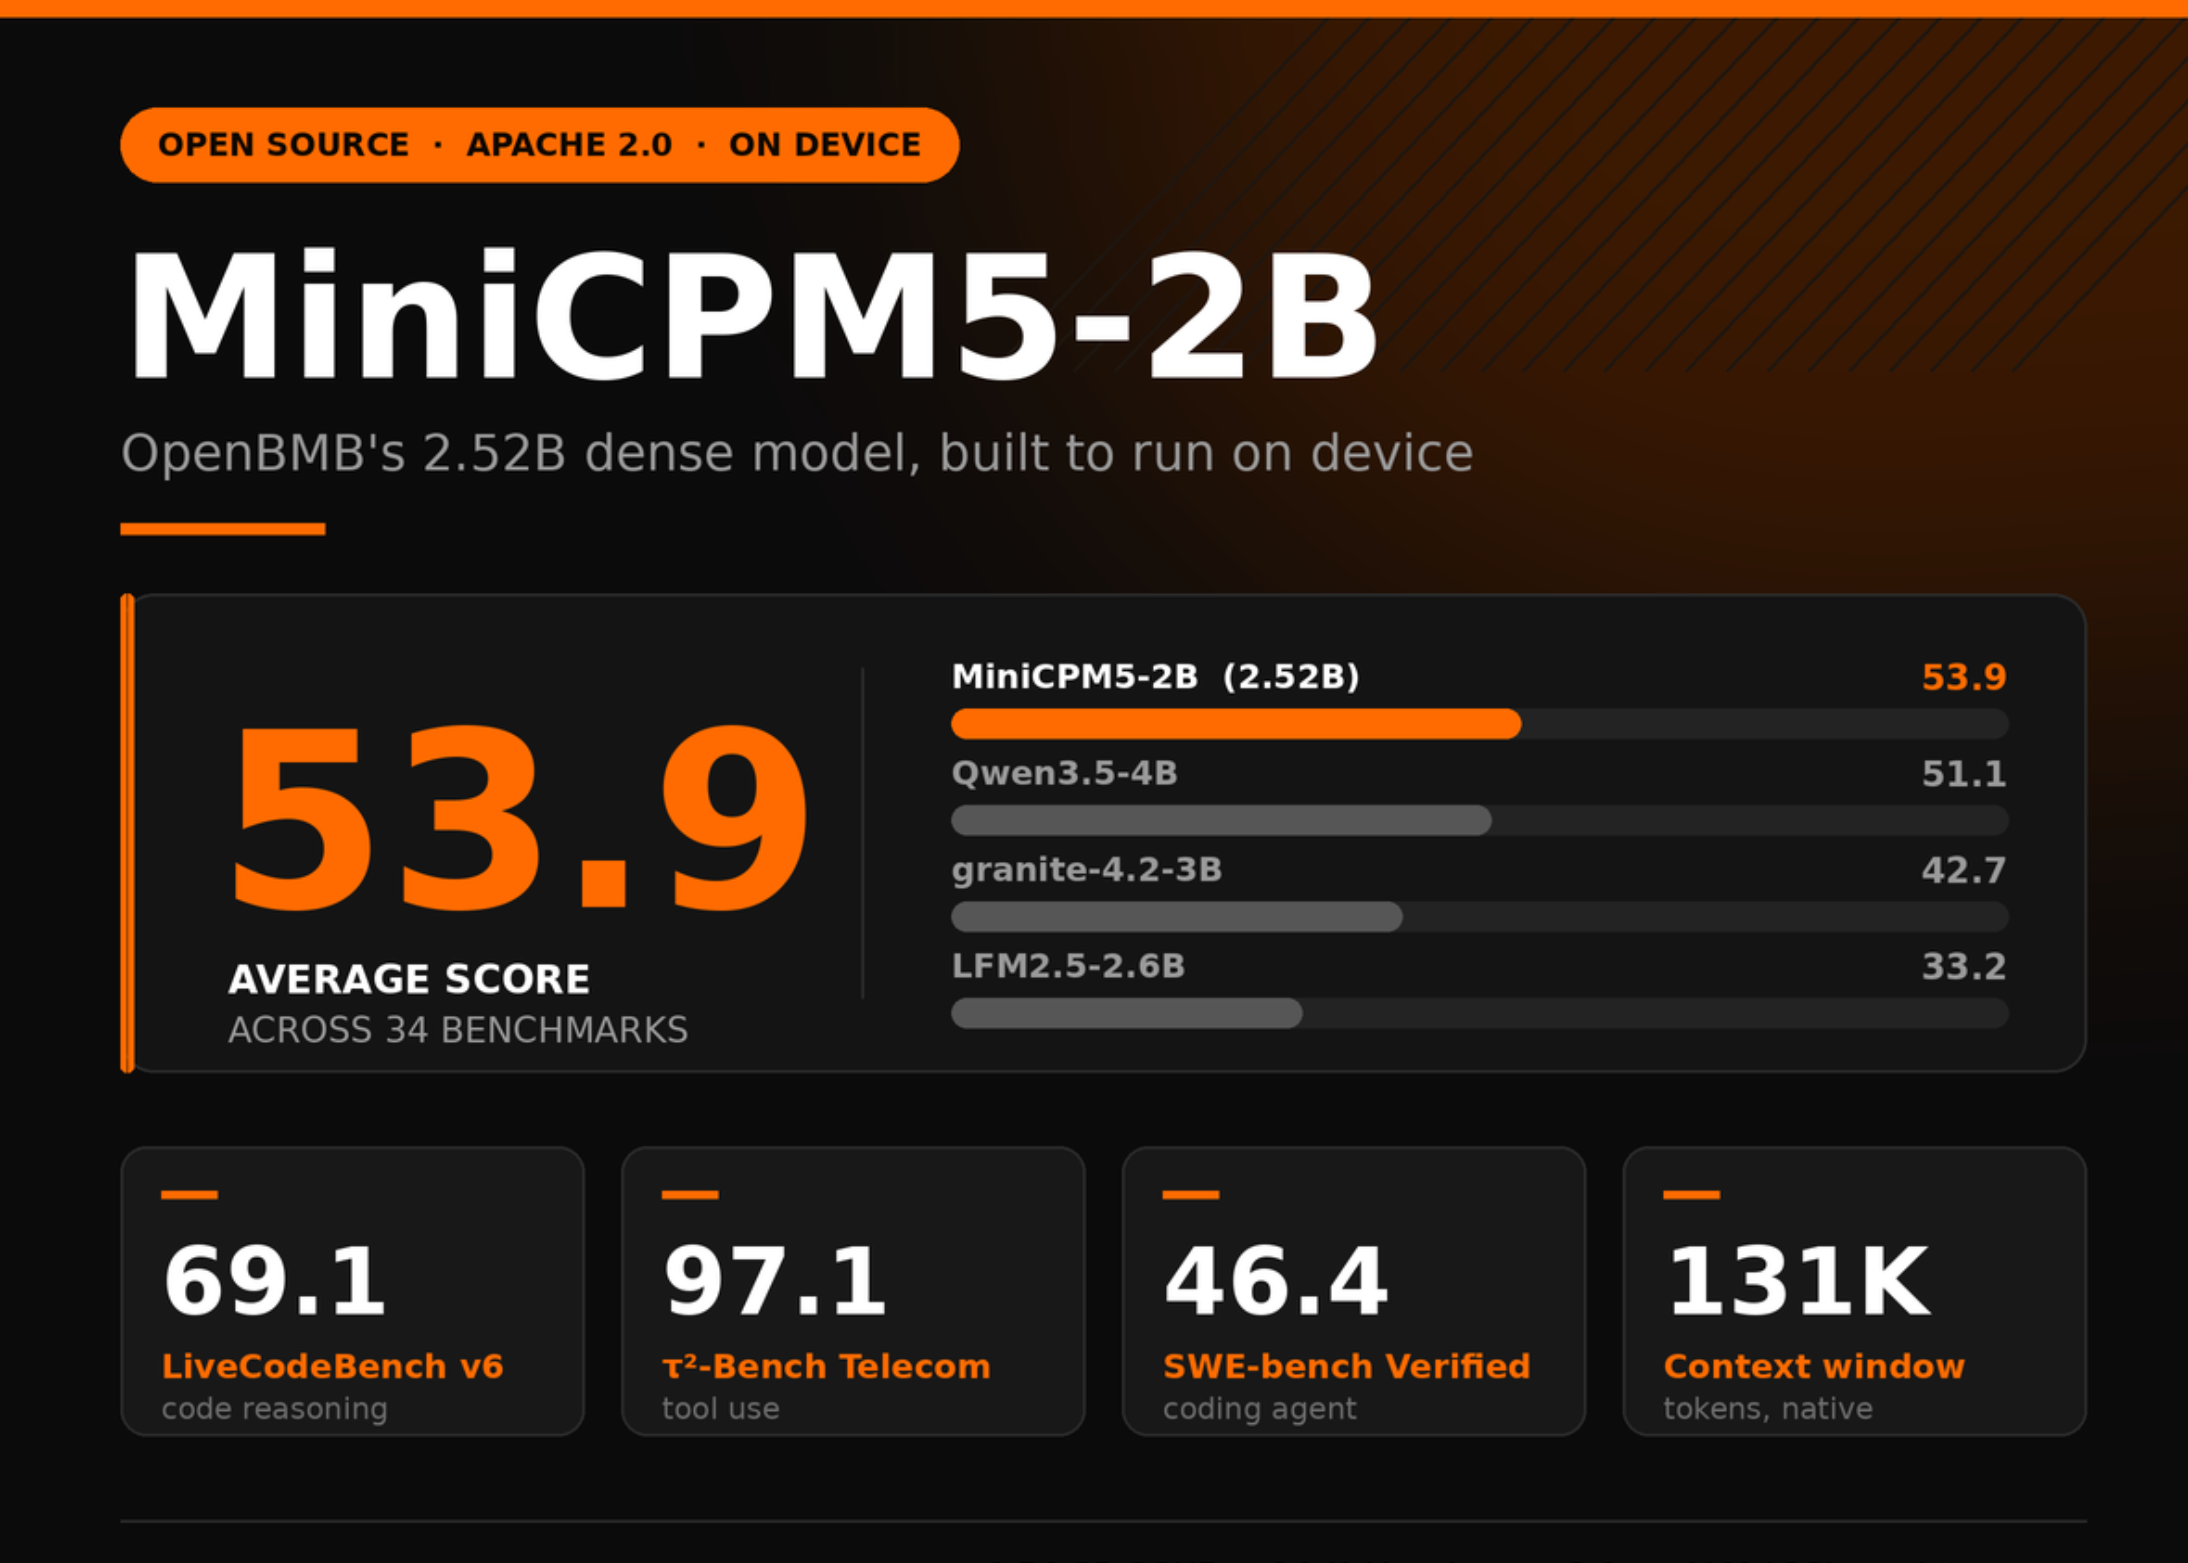
OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and
OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device
MarkTechPost
6+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
How I accelerated Python matrix ops by 1200x using Rust & C-ABI
How I accelerated Python matrix ops by 1200x using Rust & C-ABI
DEV Community
6+ day ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Decompiling activetheory.net: Zero-GC Memory Management & GPGPU Particle Systems
Decompiling activetheory.net: Zero-GC Memory Management & GPGPU Particle Systems
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
MI355X GPU type and Python SDK S3 upload reliability
MI355X GPU type and Python SDK S3 upload reliability
@daytonaio
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
24 seconds per iteration instead of 0.4. I paid for six hours of GPU compute and trained o
24 seconds per iteration instead of 0.4. I paid for six hours of GPU compute and trained on CPU the entire time.
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
CLI & Python SDK for GPU Workflows
CLI & Python SDK for GPU Workflows
Jarvislabs
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
From API to GPU, Week 6 (Part 1): A Model That Predicts, and How Wrong It Is
From API to GPU, Week 6 (Part 1): A Model That Predicts, and How Wrong It Is
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
From API to GPU, Week 6 (Part 2): Watching a Neural Network Learn
From API to GPU, Week 6 (Part 2): Watching a Neural Network Learn
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Benchmarking Serverless GPUs: Modal vs RunPod vs Replicate Cold Starts (2026)
Benchmarking Serverless GPUs: Modal vs RunPod vs Replicate Cold Starts (2026)
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Building a 200M parameter LLM from scratch in PyTorch
Building a 200M parameter LLM from scratch in PyTorch
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Three Gemma 4 Deployments on One T4G for Under $3: What the Runtime Changes, and What It D
Three Gemma 4 Deployments on One T4G for Under $3: What the Runtime Changes, and What It Doesn't
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Linux Kernel Heads Past 40.98M Lines With 7.3-rc1
Linux Kernel Heads Past 40.98M Lines With 7.3-rc1
Open Source For You
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Spark X2.5-4B & 1.7B: the only on-device models with native 1M-token context — now open so
Spark X2.5-4B & 1.7B: the only on-device models with native 1M-token context — now open source
DEV Community
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
AMD Releases ROCm 10 and Makes ROCm.AI Generally Available
AMD Releases ROCm 10 and Makes ROCm.AI Generally Available
HPCwire
1+ week ago
image
Full coverage
Related Coverage
by Keywords
by People
by Organizations
by Places
by Meta Data
by Category
by Numbers
Previous
Next